Keep models, prompts, files, and workflows on your side
Run against local llama.cpp servers, embedded runtimes, or your own controlled endpoints. The system is built for people who want AI capability without surrendering operational control.
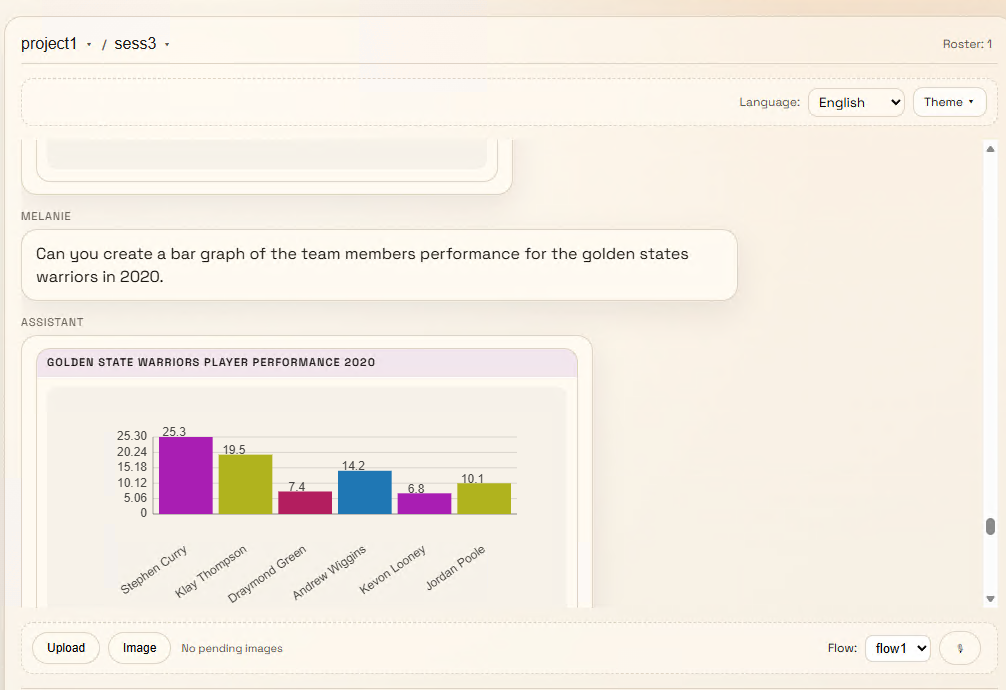
GotChat packages chat_js into a website-ready product: native embedding, self-hosted chat, model orchestration,
plugin-driven tools, shared sessions, and reusable workflows in one deployable platform.
It is not just another chat box. It is a productized local AI workspace teams can actually deploy, operate, and extend.
Run against local llama.cpp servers, embedded runtimes, or your own controlled endpoints. The system is built for people who want AI capability without surrendering operational control.
Attach tools, route tasks, automate repeatable work, and layer structured workflows on top of conversations instead of treating AI as a one-off prompt surface.
Let people sign up, join projects, work inside shared sessions, and operate from one interface while still keeping the deployment under your control.
Model deck controls, plugin management, AI routing, and runtime integration give operators visibility instead of hiding the moving parts behind a black box.
These are the product launch strengths worth leading with for chat_js.
The launch message should be simple: start small, scale into stronger hardware when your workload grows.
Modern browser, a machine that can run the app stack, and either Docker or a local Python environment.
16–32 GB RAM, local storage for models, and a dedicated GPU if you want stronger local inference and media workloads.
One machine for the workspace, optional host-managed llama.cpp servers, and room to add plugins, workflows, and team accounts over time.
1. Create a member account
2. Deploy the app stack
3. Connect your local or managed model runtime
4. Turn on the plugins and flows you need
5. Start using shared AI sessions immediately
Show the product as a workspace, not just a homepage.
Shared chat, project context, and plugin surfaces in one operating pane.
Manage model slots, llama.cpp servers, GPU routing, and launch behavior without leaving the workspace.
Compose multi-step AI workflows, plug in tools, and turn repeated tasks into reusable systems.
Layer in business logic, vertical tools, and custom integrations without abandoning the core UI.
Lead with concrete situations where a self-hosted AI workspace removes friction that hosted tools create.
Use GotChat when public SaaS AI feels operationally risky, but your team still needs a modern chat workspace they can adopt quickly.
Combine chat, local runtimes, plugins, workflows, and session management instead of stitching separate dashboards together.
Launch a shared AI environment for support, research, operations, or product teams without sending sensitive work outside your stack.
Fork it, patch it, run it locally, and make the product yours. The value is not only the UI. It is the ability to operate and evolve the system directly.
This launch page is designed to convert visitors into members first, then pull serious operators and contributors into the repository.
That is the right product launch motion for chat_js: get people into the product fast, and give technical users a clear path to inspect and extend it.
Sign up, deploy, connect your models, and start using GotChat as a working AI workspace instead of a demo.